Image to prompt: read a reusable prompt from any photo
Upload an image, choose what the analysis should emphasize, and review the returned prompt before reusing it. The sections below cover what an image-to-prompt tool can and cannot recover, how different models read the result, and the rights rules that apply.
Creative settings
Image to Prompt
The prompt structure will be adapted to the target workflow.
Advanced options
Generated result
Complete the settings and generate. Your result will appear here without leaving the page.
Examples
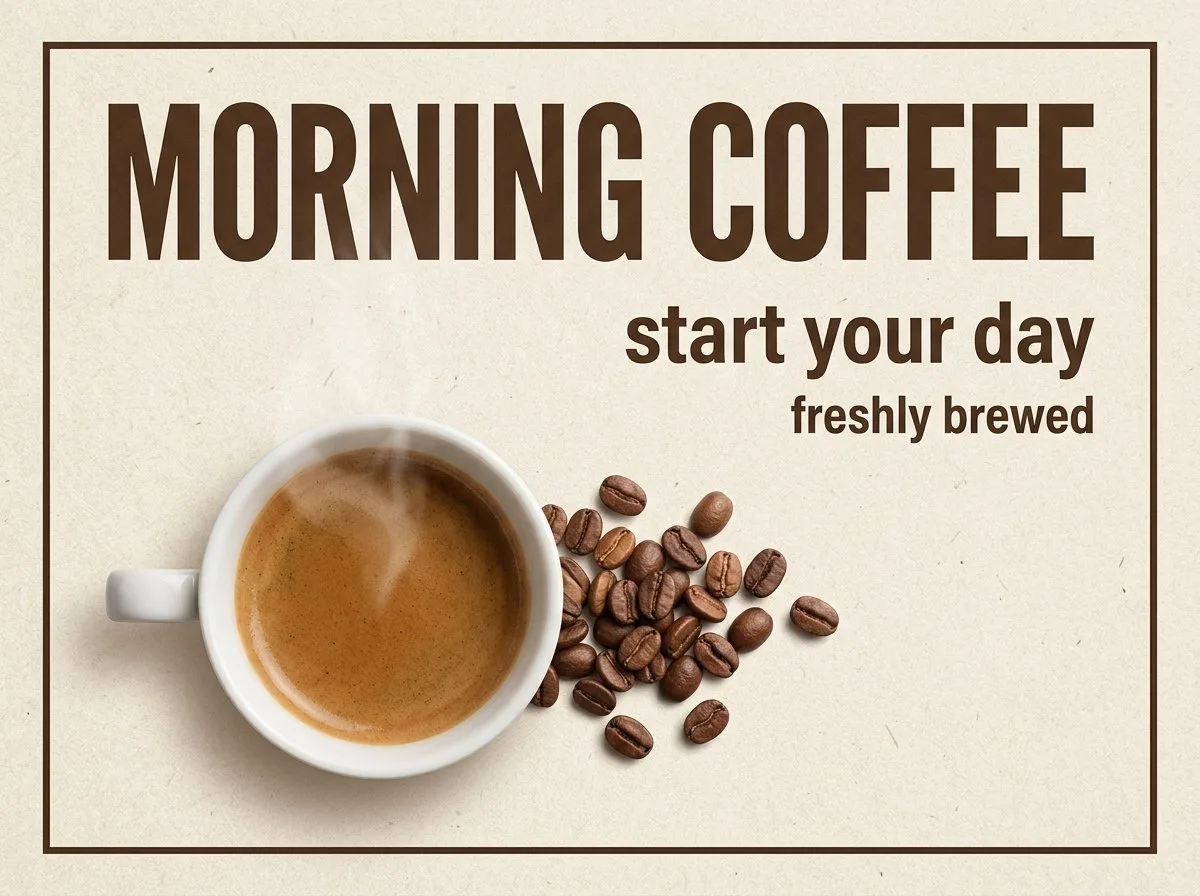
Minimalist cafe poster on warm off-white textured paper with a thin dark-brown double border. Oversized condensed sans-serif headline MORNING COFFEE in deep espresso brown spans the top; a right-aligned subhead reading start your day sits beneath it with freshly brewed in a smaller weight below. A white ceramic cup of coffee seen from directly overhead sits in the lower left, its crema swirl and a faint wisp of steam visible, with roasted coffee beans scattered to its right in a loose arc. Flat studio lighting, muted earthy palette of cream, tan and brown, generous negative space, print-ready 4:3 layout.
A print-style cafe poster. What a reverse prompt has to capture here is the layout and the type hierarchy, not just the cup: the border, the oversized headline and the right-aligned subheads are what make it a poster rather than a photo.
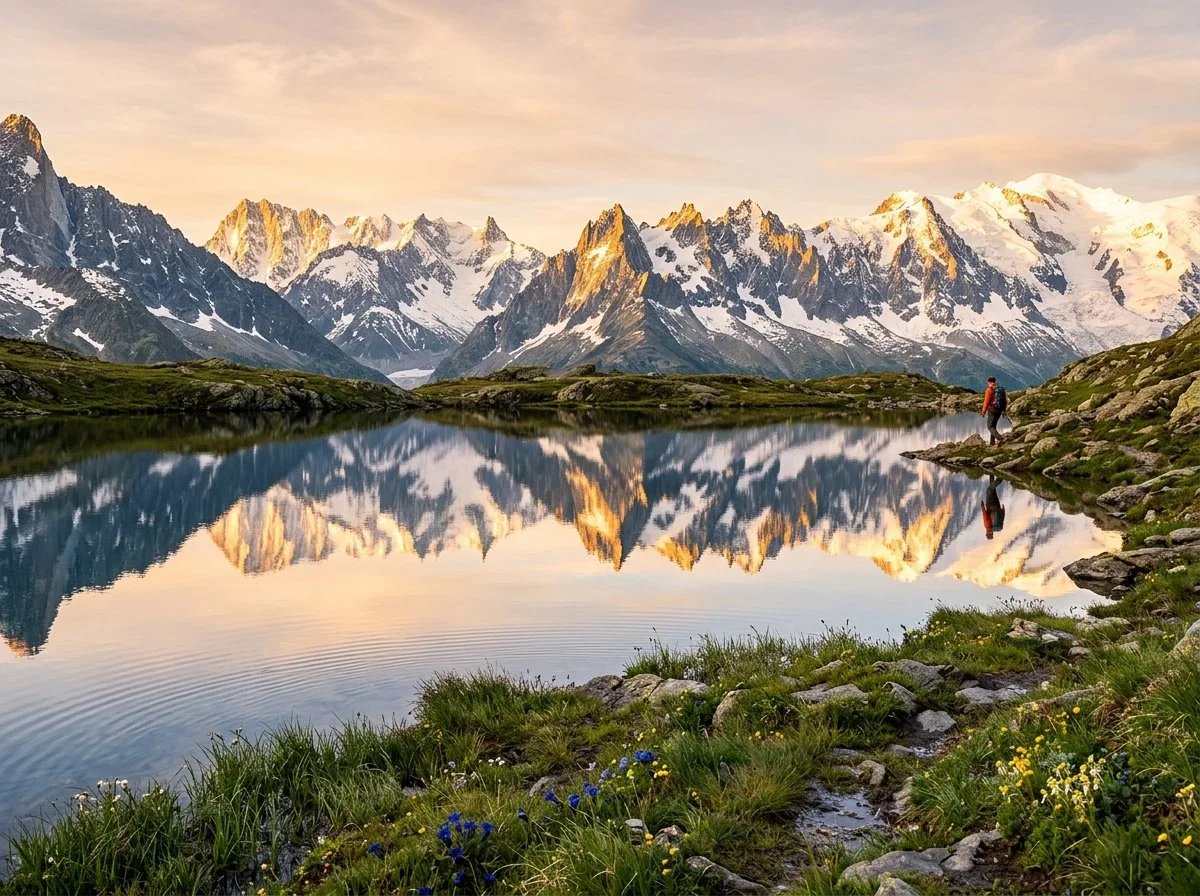
Alpine landscape at sunrise: a mirror-still glacial lake fills the foreground and reflects a jagged snow-capped range across its full width, the peaks rim-lit warm gold on their right faces against a pale peach and blue sky. A single hiker in a red jacket and backpack walks the grassy right-hand shore, small in frame. The foreground holds dew-covered alpine grass, rocks and scattered blue and yellow wildflowers, with the nearest flowers just out of focus. Ultra-wide 16 mm feel, deep focus, high dynamic range, natural color grading.
A landscape photograph where almost every strong word is verifiable on sight: mirrored reflection, rim-lit peaks, and the one figure that supplies scale.
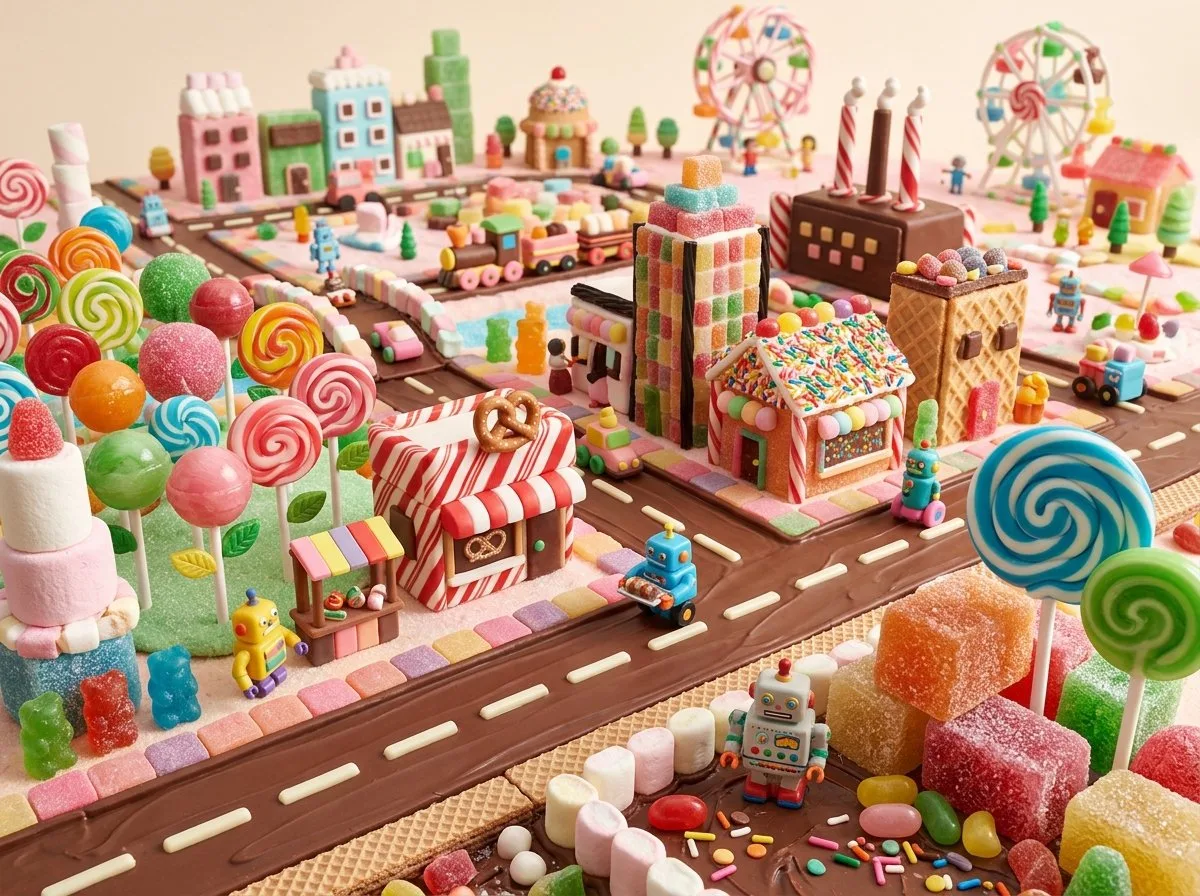
Macro diorama photograph of a miniature city built entirely from candy. A chocolate-paved road with white icing lane markings curves through the scene; buildings are wafer, gingerbread and red-striped candy blocks with sprinkle rooftops and a pretzel sign. Lollipops and gummy-bear trees line a green candy park with a marshmallow tower, gummy robots and a candy train populate the streets, and a white candy Ferris wheel turns in the background. Soft warm studio light, pastel palette, shallow depth of field with the nearest candy jars sharp, playful surreal mood, 4:3.
A miniature set built from sweets. The prompt has to name the material of each element, because candy is what carries the effect.
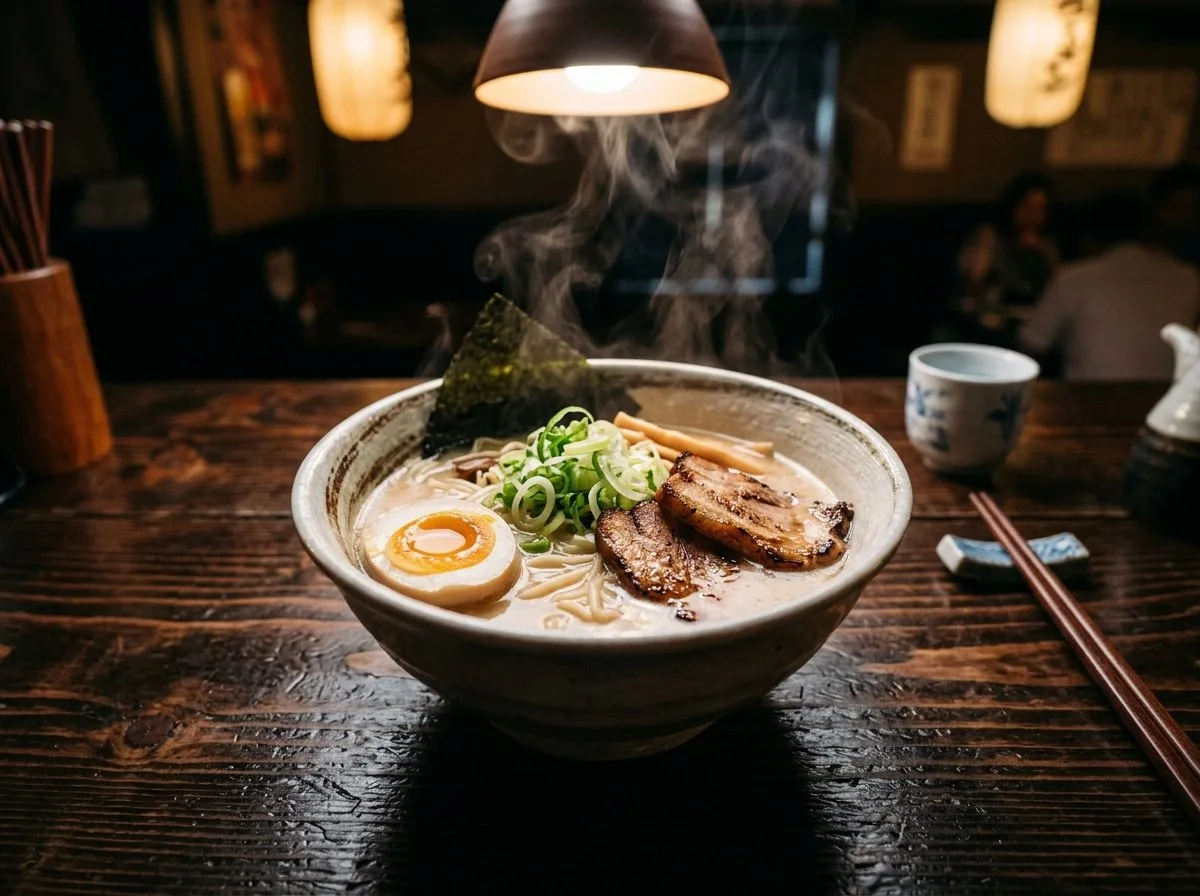
Moody restaurant still life of a steaming bowl of tonkotsu ramen on a dark, wet-look wooden table. A shallow speckled-rim bowl holds cloudy pork broth, curly noodles, two slices of seared chashu, a halved soft-boiled egg with a jammy yolk, a sheet of nori, bamboo shoots and a mound of chopped scallions; steam curls upward through the light. Warm hanging lamps glow overhead against a blurred background of diners, with a chopstick holder and a folded napkin at the left edge. Low-key 50 mm shot at a wide aperture, warm amber highlights, deep shadows, 4:3.
A low-key food shot. Here the reverse prompt should describe the light before the ingredients: the warm lamp, the steam catching it, and the bokeh that sets the restaurant behind.
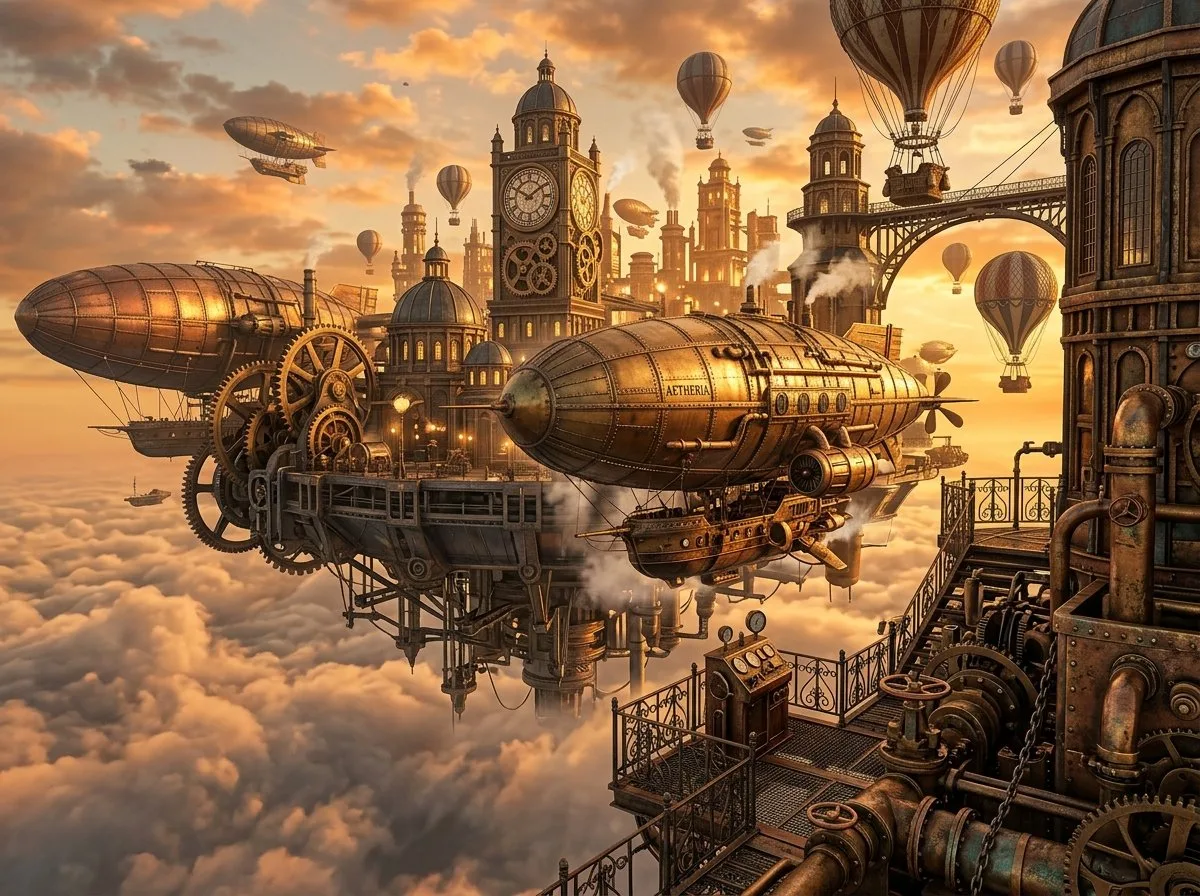
Sweeping steampunk cityscape above a sea of clouds at golden hour. An ornate riveted brass airship with an AETHERIA nameplate hangs mid-frame right, its gondola trailing pipes and steam; smaller dirigibles and hot-air balloons drift through the amber light. To the left a floating platform city of copper domes, clock towers with exposed gearworks and iron bridges rises out of the cloud layer, with a second airship docked at upper left. The sun flares behind cumulus clouds, and the foreground right shows an industrial balcony of pipes, valves, gears and railings. Ultra-detailed digital painting, warm bronze and gold palette, dramatic backlighting and volumetric haze, cinematic composition.
A digital illustration. Long prompts are the norm here: material, era, machinery and light all have to be stated, and one readable nameplate is worth writing down exactly.
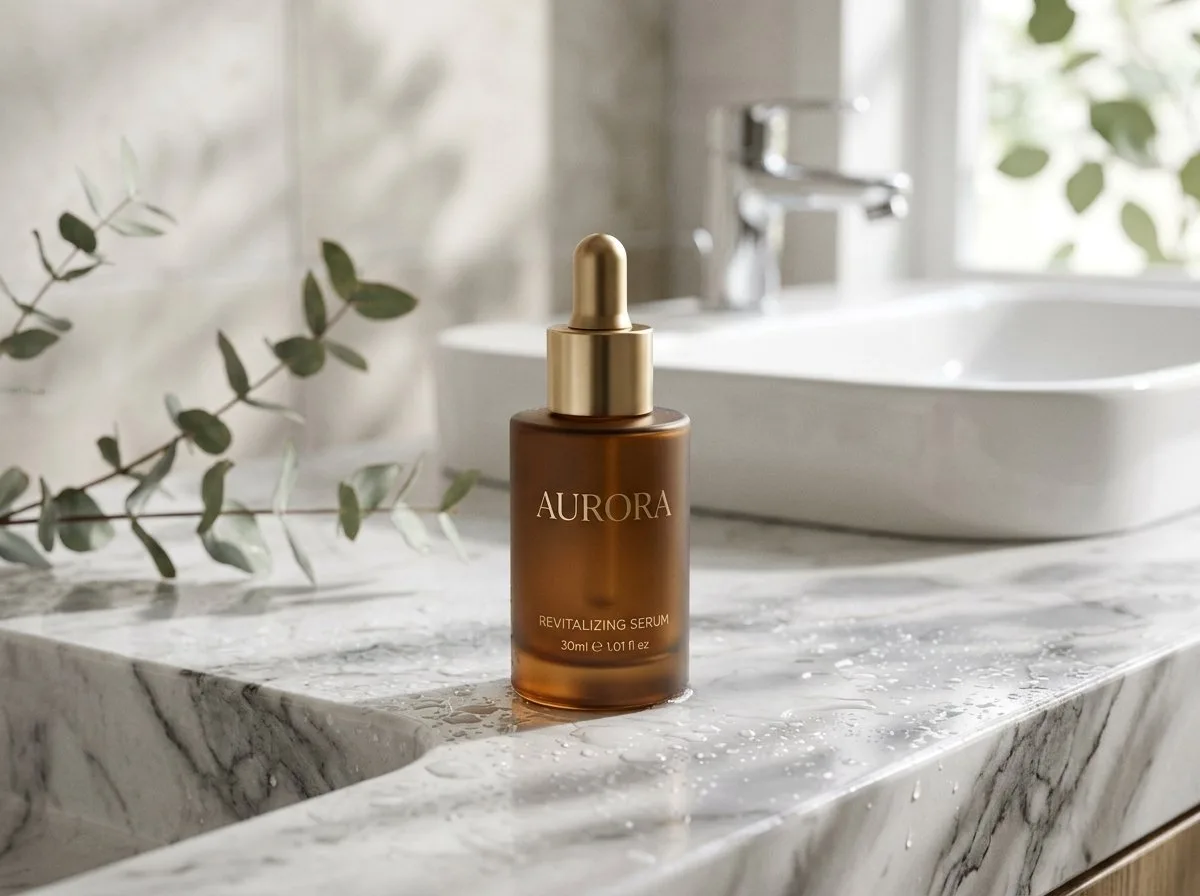
Editorial product shot of an amber glass dropper bottle standing on a wet white marble countertop, water droplets beaded across the surface. The bottle carries a brushed gold dropper cap and a thin gold serif label reading AURORA, with REVITALIZING SERUM and 30 ml e 1.01 fl oz beneath it. A sprig of eucalyptus enters from the left, softly out of focus; behind it a white ceramic basin and a chrome faucet sit in a bright, blurred bathroom where daylight falls through a window with greenery. Soft raking daylight from the right, high-key palette of white, grey marble veining and warm amber, shallow depth of field, e-commerce hero framing, 4:3.
A product shot. The reverse prompt has to reproduce the light path and the wet surface, and it should transcribe the label lettering word for word.
What an image-to-prompt tool does, and what it cannot do
An image-to-prompt tool reads the visible evidence in a picture — subject, composition, style, lighting, color and lens character — and writes a new text prompt that describes it. It does not recover the words the original author typed. Unless the file still carries its generation metadata, the original prompt is gone; what you get is a faithful reconstruction, not the original text.
- It can recover what is visible: subject, arrangement, art style, lighting, camera feel, color treatment, medium.
- It cannot recover the author's exact wording, negative instructions that left no visible trace, or hidden parameters such as sampler settings.
What one upload returns
One upload returns an editable prompt organized the way image models consume text: subject first, then composition, style and medium, then lighting, lens and color, then quality and format words. You can copy it into any text-prompt model, or run it directly with the image models in this workspace.
Four steps from a photo to a prompt you can reuse
The workspace walk is deliberately short.
- Pick an image you are allowed to process and upload it.
- Set an optional focus — composition, subject, style or lighting — when you want the analysis to emphasize one layer.
- Review the server-side quote, submit, and read the returned prompt.
- Edit the wording to match your target model, then reuse it here or anywhere else text prompts are accepted.
Prompt order changes with the target model
The same description lands differently depending on who reads it. Image models do not share one grammar, so a prompt that works as-is for one family wastes its strongest words in another. The table shows the order this tool writes in, and how to re-cut it per family.
| Target model family | How it reads a prompt | Lead with |
|---|---|---|
| Midjourney-style models | Short, comma-separated phrases; whole-sentence prose wastes attention | Subject and medium, then style |
| Stable Diffusion family | Tag-and-weight style; explicit keywords beat connectives | Subject, then style tags and quality words |
| Flux and Gemini-class models | Natural language, full sentences, layout instructions | A plain description of the scene |
| Text editors and agents | Anything structured | A labeled list of visual attributes |
Some images still carry their original prompt inside the file
Before reverse-engineering anything, check whether the prompt is still attached. Stable Diffusion WebUI writes the full positive and negative prompt, steps, sampler, CFG scale, seed and model hash into a PNG tEXt chunk named parameters; JPEG and WebP exports carry an EXIF UserComment; ComfyUI embeds the entire workflow JSON. If that metadata is present, you can copy the original prompt out verbatim — no reconstruction needed.
The catch is that this metadata is fragile. Re-uploading to Discord, X, Reddit, Facebook or Telegram strips it, and so do screenshots and any second encoding. A file that has travelled through a social platform almost never still carries its prompt — which is when reconstructing from visible evidence is what you need.
Four prompts to copy, sorted by model family
Now the reverse direction: prompts whose shape is worth copying when you write your own, one per family. Replace the bracketed parts.
editorial photograph of [subject], [setting], soft window light, 35mm, muted color grade --ar 3:2
[subject], [style] style, detailed texture, cinematic lighting, sharp focus, [color palette], high detail
A [medium] of [subject] in [setting]. The composition places [key element] in the foreground; lighting is [lighting description]; the palette leans [colors]. Rendered with [lens or camera feel].
[shot type] of [subject], [action or pose], wearing [details], in [environment], [time of day], [lighting description], [style reference], [aspect ratio]
Free, no sign-up, unlimited: what those words mean here
Search results for this keyword are full of tools pitched as free, unlimited and no-sign-up. That is their pitch, not this site's. Here every request shows a server-side quote before you submit, and the task ledger is the final billing record. Nothing is advertised as unlimited because nothing is — what is callable, and at what price, follows the live catalog.
How close the result will be, and where it drifts
A returned prompt is strongest on what a viewer can see: subject, composition, medium, lighting, palette. It drifts on what does not survive into pixels: exact text rendered inside the image, brand marks, negative instructions, and any parameter the original tool kept to itself. A useful boundary case is Midjourney: its seed is an integer between 0 and 4,294,967,295, it can only be recalled for your own jobs, and it does not encode style — so no tool can read a Midjourney image and hand back the seed that reproduces the look.
- Close: subject, pose, composition, art style, lighting, color treatment.
- Drifts: in-image text, logos, negative prompts, hidden settings such as sampler or guidance.
Six uses beyond copying a look
The output is plain text, so it fits anywhere a description fits.
- Alt text and captions for accessibility or a content library.
- Style continuity: describe a house style once, reuse it across a series.
- Prompt-writing practice: see how a look you admire decomposes into words.
- Documenting your own generations when the original prompt is lost.
- Mood-board analysis: turn references into comparable text.
- Brief hand-off: give a designer or a client a precise description of a reference.
Rights, consent, and photographs of real people
Only upload images you have the rights to process. For photographs of real people, get consent before running an analysis, and do not use the result to impersonate anyone. Brand logos and trademarked characters deserve the same caution in both directions — in the image you upload and in the prompt you reuse. The tool's output does not grant you any rights you do not already hold.
Questions
Does it reproduce the original prompt?
No. It writes a new description from the visible evidence in the image. The original prompt is only recoverable when it still travels inside the file's metadata — a PNG parameters chunk, an EXIF UserComment, or a ComfyUI workflow.
Can it extract a prompt from a PNG?
Yes, when the PNG still carries generation metadata from Stable Diffusion WebUI or ComfyUI. Metadata is stripped by re-uploads to social platforms, screenshots and re-encoding, so files that have circulated usually have none; the tool then reconstructs from visible evidence instead.
Can I reuse the result with the image models here?
Yes. The output is plain text: copy it into the image workspaces on this site or edit it first. Results always depend on the target model and your settings.
Which model family is the result written for?
The default order suits natural-language models. The section on prompt order shows how to re-cut it for short-phrase and tag-style families.
How accurate is the reverse prompt?
Strong on visible attributes — subject, composition, style, lighting, palette; weakest on in-image text, logos and anything invisible in the final pixels. Expect a close reconstruction, not a verbatim recovery.
Does a Midjourney seed let me recreate an image?
No. The seed is an integer between 0 and 4,294,967,295, retrievable only for your own jobs, and it does not carry style. No tool can read a look back out of a seed.
What happens to my upload?
The image is processed for your task inside this workspace and is not published by the site. Process only images you are allowed to use.
How much does it cost?
Each request shows a server-side quote before you submit, and the server ledger is the final billing record. The live catalog governs what is callable and at what price.
Is it free and unlimited?
No — and pages promising that usually hide the cost somewhere else. Here, every request is quoted before submission, so you approve the price first.
Can I upload photos of real people?
Only with the rights and consent to do so, and the output must not be used to impersonate anyone. See the rights section above.
Explore next
Nano Banana 2.1
Nano Banana 2.1 on Gemini 4 Argon: open modes, published parameters and limits, prompt structure, failure recovery, and how to choose 2.1, 2 or Lite.
Nano Banana 2
Nano Banana 2 is Gemini 3.1 Flash Image: 4K output, 14 reference images, in-image text and search grounding. Official specs, limits and prompt frameworks.
GPT Image 2.5
Create or edit images with GPT Image 2.5 (ChatGPT Images 2.5): up to 50% faster, precise targeted edits, 3,840 px output. See specs, pricing and prompts.