Gemini 3.7 Flash
Gemini 3.7 Flash is a previous-generation multimodal Flash model designed for coding, agentic workflows and long-context tasks, balancing fast responses with capable reasoning.
Examples
Input
DeepSWE v1.1: long-horizon software engineering tasks.
Output
Google's model card reports 65.3% for Gemini 3.7 Flash versus 48.6% for Gemini 3.6 Flash. The result reflects the vendor's evaluation setup and does not guarantee the same outcome for every prompt.
Google's August 2026 model card snapshot for Gemini 3.7 Flash; a vendor-reported benchmark, not a test run by this site.
Current status: deprecated by Google, available in this workspace
Google marks gemini-3.7-flash as deprecated and says requests to that model code are automatically routed to gemini-3.8-flash. Separately, this site's live catalog currently returns gemini-3.7-flash as preview, callable and priced. The selector therefore exposes the gateway entry but does not claim that Google still serves a distinct 3.7 backend.
Official specifications
Google documents text, image, video, audio and PDF input with text output. The model card describes Gemini 3.7 Flash as based on Gemini 3.6 Flash, with improvements to core reasoning and agentic video understanding. Google prices the model at $0.75 per million input tokens and $3.75 per million output tokens as an introductory rate through December 31, 2026; from January 1, 2027 the rates double to $1.50 and $7.50.
Published limits
- 1,048,576 input tokens
- 65,536 output tokens
- March 2026 reported knowledge cutoff
- 2026-08-13 model-card publication date
Google API pricing
- $0.75 input / 1M tokens introductory, through Dec 31, 2026
- $3.75 output / 1M tokens introductory, through Dec 31, 2026
- $1.50 / $7.50 from Jan 1, 2027 introductory rates double
- $0.075 cached input / 1M tokens about one tenth of the input price
Tools and runtime boundaries
Google’s reference page lists caching, code execution, preview computer use, file search, function calling, Maps grounding, search grounding, structured outputs, URL context and low, medium or high thinking. The live catalog entry used here currently declares streaming and vision, but no web search or reasoning control. This workspace follows the live gateway capabilities, quote and ledger rather than enabling controls from documentation alone.
Vendor-reported benchmark snapshot
Google’s August 2026 model card reports improvements over Gemini 3.6 Flash across coding and agentic evaluations. These are provider results, not tests performed by this site.
Source: https://deepmind.google/models/model-cards/gemini-3-7-flash/
| Benchmark | Gemini 3.7 Flash | Gemini 3.6 Flash |
|---|---|---|
| Artificial Analysis Intelligence Index | 56 | 52 |
| FrontierCode 1.1 | 43.6% | 34.4% |
| DeepSWE v1.1 | 65.3% | 48.6% |
| Terminal-bench 2.1 | 85.8% | 78.0% |
| AutomationBench | 30.4% | 17.0% |
| GDP.pdf | 34.0% | 22.0% |
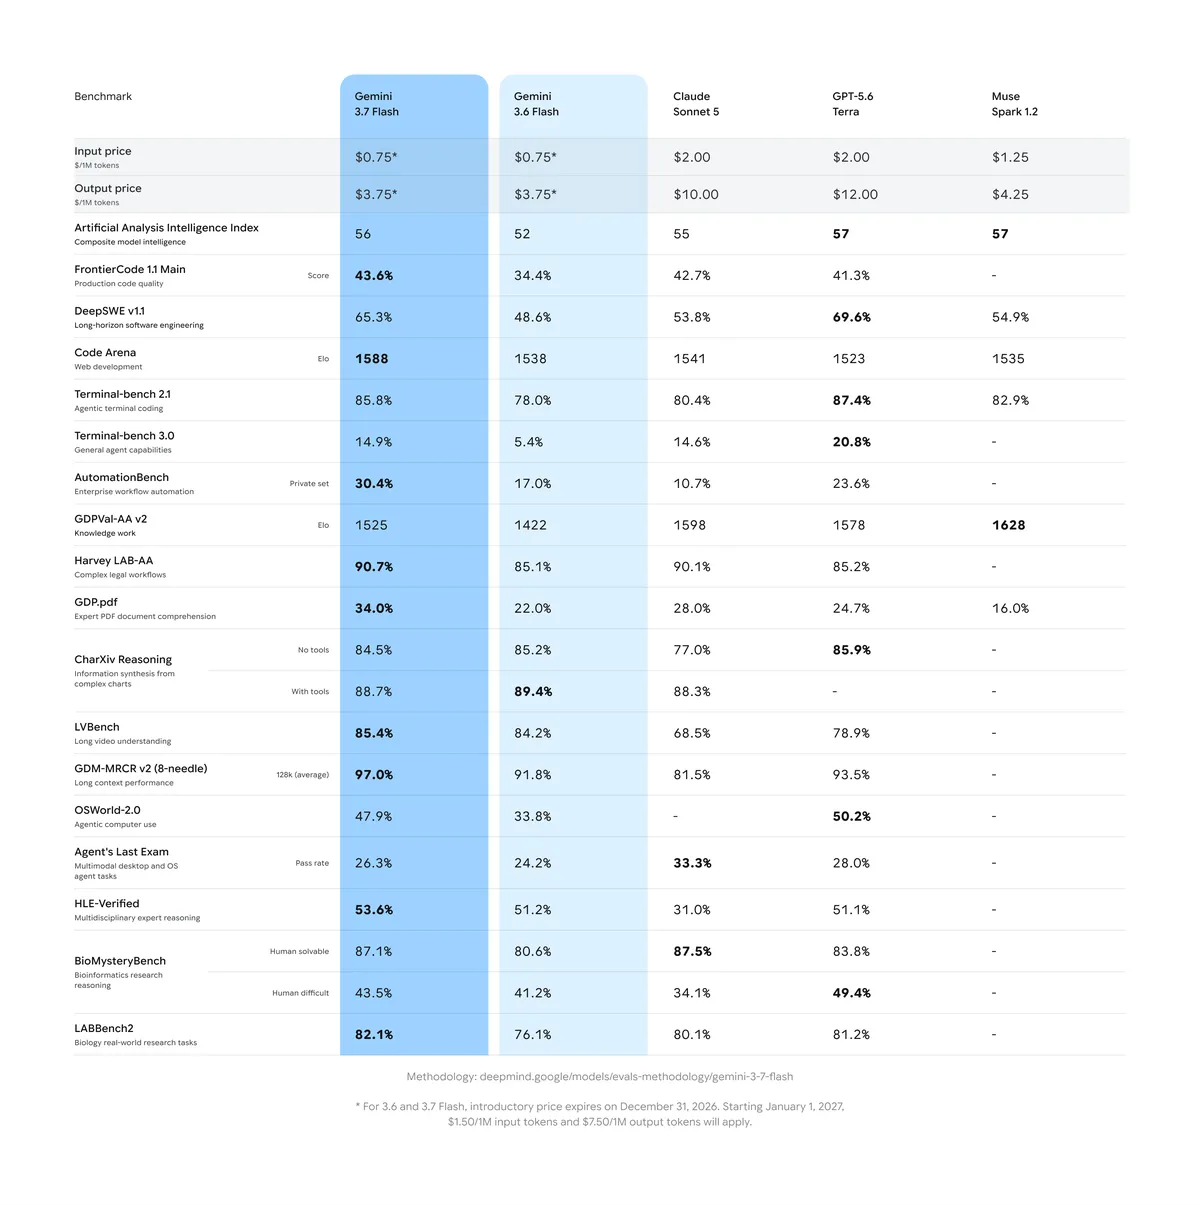
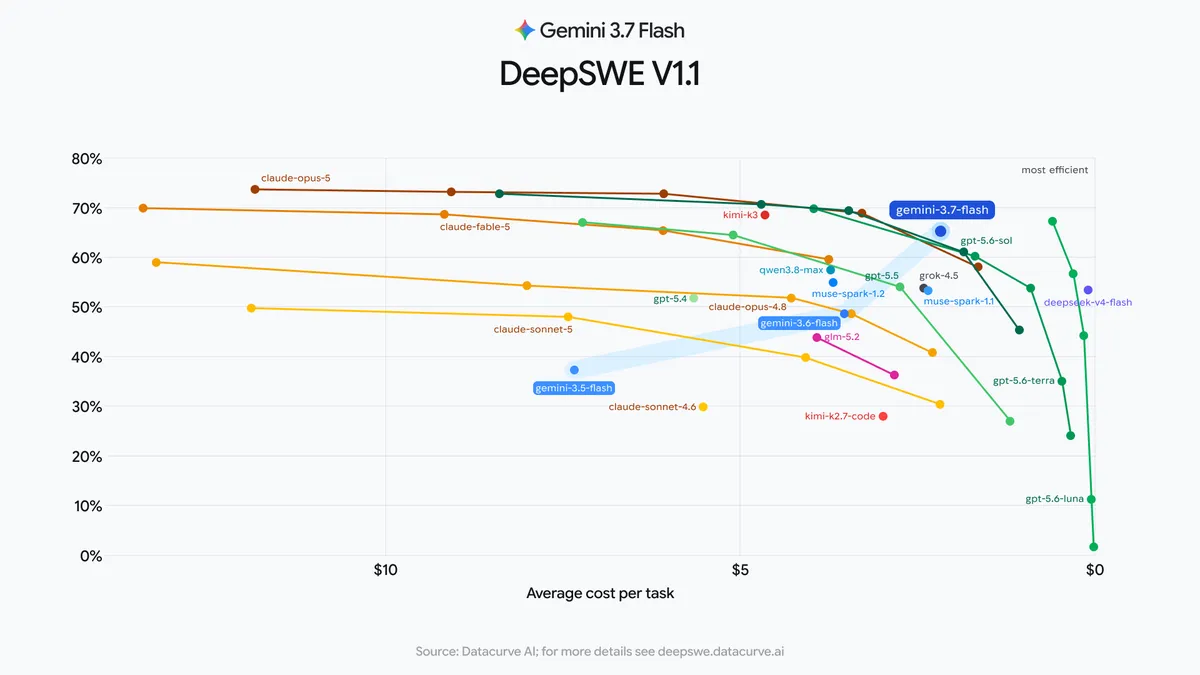
Both figures are reproduced from Google's Gemini 3.7 Flash announcement; evaluation methodology is described in the original post. blog.google ↗
Prompt patterns that work well
Two patterns use this model's strengths: fast, cheap iteration and long-context summarization. Replace the bracketed parts and paste them into the workspace.
Read the attached document and extract every [clause / metric / deadline] matching this rule, in order of appearance, with the section noted, and flag conflicts between sections. Rule: [your rule].
Draft [deliverable] at the low thinking level first. If any part needs deeper reasoning, list those parts and redo only them at the high level.
Use the site-scoped model entry
Open the chat workspace, select Google Gemini 3.7 Flash and review the server quote before sending. Because Google now redirects the official model code to 3.8 Flash, treat the live response metadata and server ledger as the execution and billing record.
Questions
Is Gemini 3.7 Flash still an active Google API model?
Google now marks gemini-3.7-flash deprecated and says requests are automatically routed to gemini-3.8-flash.
Why does this site still show Gemini 3.7 Flash?
this site's live catalog currently returns gemini-3.7-flash as preview, callable and priced. The site exposes that gateway entry and states Google’s deprecation separately.
What are its token limits?
Google documents up to 1,048,576 input tokens and 65,536 output tokens.
Can it accept images and PDFs?
Google documents text, image, video, audio and PDF input. The current live catalog entry exposes vision support; available upload controls remain governed by the live catalog.
Is this a Google website?
No. This is an independent multi-model workspace and is not affiliated with, endorsed by or operated by Google.
How much does Gemini 3.7 Flash cost?
Google's introductory API price is $0.75 per million input tokens and $3.75 per million output tokens through December 31, 2026, doubling to $1.50 and $7.50 on January 1, 2027. Cached input reads at about one tenth of the input price. Charges in this workspace are set by the server-side quote and settled in the task ledger.
Should I still use Gemini 3.7 Flash for new work?
Google routes requests to the deprecated gemini-3.7-flash code to Gemini 3.8 Flash automatically. For new work, 3.8 Flash is the model to pick; this page remains for tasks that explicitly target the 3.7 entry.
Explore next
Gemini 4 Argon AI chat
Chat with Gemini 4 Argon through this site's live catalog, with multimodal input, required reasoning and a server quote before every request.
Gemini 3.8 Flash
Chat with Gemini 3.8 Flash, served here today. Specs, published benchmarks, pricing and prompt patterns, plus how it differs from Gemini 4 Argon.
Gemini 4 Argon
Gemini 4 Argon guide: official specs, 1M context, benchmarks, intro API pricing and known limits, plus direct access through the live chat workspace.